Measured machine learning. Written in Uzbek.
PySphere is a library of machine learning and AI books for Uzbek-speaking students. Six books, 174 chapters, free, no login.
Every chart and every number in them came out of code that was executed. Nothing was typed in by hand to look convincing.
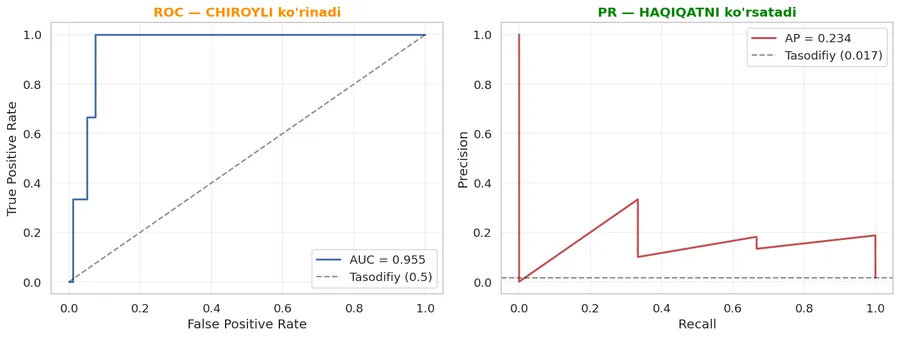
One model, one dataset. The ROC curve reports AUC 0.955 and the precision-recall curve reports AP 0.234. Both are correct. Only one of them tells you the model is useless.
Two books are in English. Four are not.
ML Book and SQL and Seaborn are in English in full: 48 and 25 chapters, every block of code run again after translation and every output printed as it came out. The other four books are written in Uzbek. English material on machine learning is abundant and excellent. Measured Uzbek material did not exist, which is the only reason these books do.
What crosses the language line: the code is Python, every technical term is deliberately kept in English — gradient descent stays gradient descent, leakage stays leakage — and figures, tables and datasets read the same in any language. If you already work in ML, you can open any chapter and follow it by the code alone.
Six books. 174 chapters. Free.
Chapter text is Uzbek, except the ML Book and SQL and Seaborn. Code, figures and datasets are not.
What "measured" means here
2 212 runnable code blocks. 190 figures. 593 339 words. Every figure was produced by the code printed beside it.
Where a measurement contradicted what I expected, the failed attempt stayed in the book with its number. The chapter on ROC versus precision-recall exists because a model reached 0.999 accuracy and caught none of the ten fraudsters in the data.
import numpy as np
from sklearn.metrics import accuracy_score, recall_score

y = np.zeros(10000, dtype=int)
y[:10] = 1                    # 10 of 10 000 are fraud
pred = np.zeros(10000, dtype=int)       # call everyone clean

print("accuracy :", round(accuracy_score(y, pred), 3))
print("recall   :", round(recall_score(y, pred), 3))
The parts that cost money
Data Analytics — 32 chapters, Excel through dashboards, with SQL, pandas, statistics and A/B testing. Six chapters are open as a preview; the rest is 800 000 UZS once. It is read on this site: nothing is emailed and no files are handed out.
The course is a different thing and it is monthly — a video per chapter, homework that actually gets marked, and a person who answers your question.
Who wrote this
Abulqosim Rafiqov. I teach this material, and I wrote the books because I lost a week of my own time to a metric that lied to me.
- Access and payment: @RafiqovAbulqosim02
- New chapters: t.me/pysphere_kanal